> For the complete documentation index, see [llms.txt](https://upgrade-platform.gitbook.io/upgrade-documentation/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://upgrade-platform.gitbook.io/upgrade-documentation/6.6/creating-an-adaptive-experiment/thompson-sampling-configurable.md).
# Thompson Sampling (Configurable)
Mooclet Adaptive Algorithm
### Summary
Thompson Sampling is an "adaptive" experiment type where the condition distribution will update depending user on user feedback. "Winning" conditions that accumulate substantively more successes (and fewer failures) than other conditions will see their distribution % go up, and "losing" conditions will trend downward, with the idea that a clear winner will eventually trend toward 100%.
### `ts_configurable` parameters
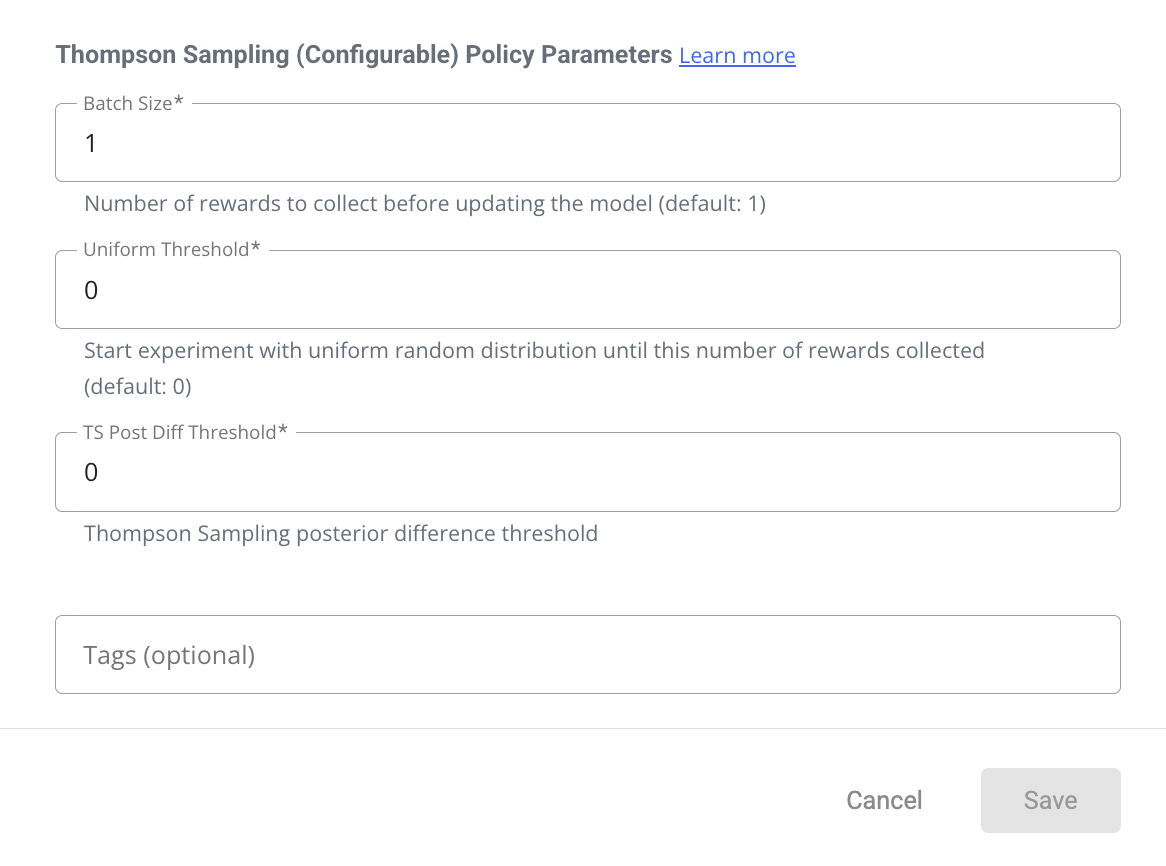
There are 3 editable parameters when creating a Thompson Sampling experiment:
{% hint style="info" %}
FYI: These values CAN be changed while the experiment running.
{% endhint %}
`batch_size`: integer (default: 1, min: 1)\
"Batch Size" means how many rewards to collect before updating the model.\
\
For example, a batch size of 1 will result in the model being updates after every reward is collected.\
A batch size of 100 will wait until 100 rewards have been collected before adjusting the weights, and then again after another 100, and so on...\
\
Ideally for Thompson Sampling, data should be updated as after every piece of feedback comes in. However, batching could be valuable for performance if a lot of traffic, for instance.
`uniform_threshold`: integer (default: 0, min: 0)
"Uniform Threshold" represents a "burn-in" number of rewards to collect with equally weighted arms before the first model update, after which the model will updated after every `batch-size` number of rewards received.
`tspostdiff_thresh` : float (default 0.0, min 0.0, max 1.0)\
\
"TSPostDiff\_Thresh" controls when the system considers one option (arm, intervention, content, etc.) to be meaningfully better than another based on their posterior reward distributions.\
\
What this means mechanically is basically that the system will sprinkle in equal-weighted-random draw chances when the conditions are producing similar results from their beta distribution draws. Closer to 0 means the difference has to be narrow, while closer to 1 means the difference is wide.\
\
The theory is that because of variance in small sample sizes, Thompson-Sampling results could prematurely crown a winner without a fair fight; when given enough input it should correct eventually, but studies may not have the luxury of a huge pool of participants. Allowing for some chance of the losing condition to get some extra shots to gather some more data by giving it a coin-toss here and there instead of 1% chance.
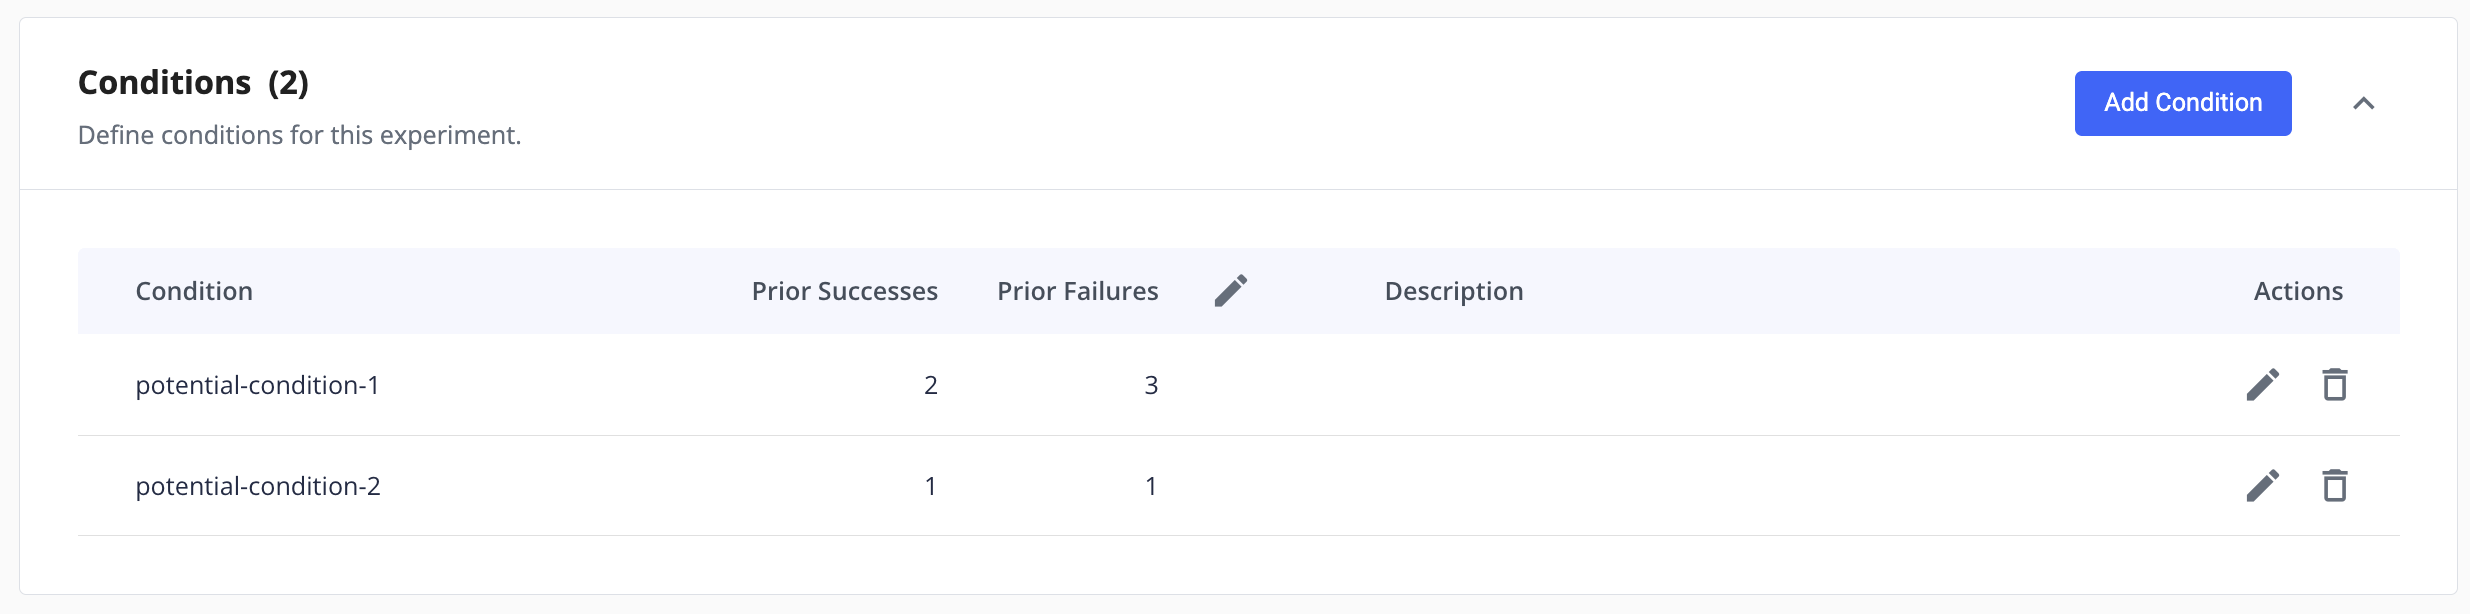
#### Priors
\
\
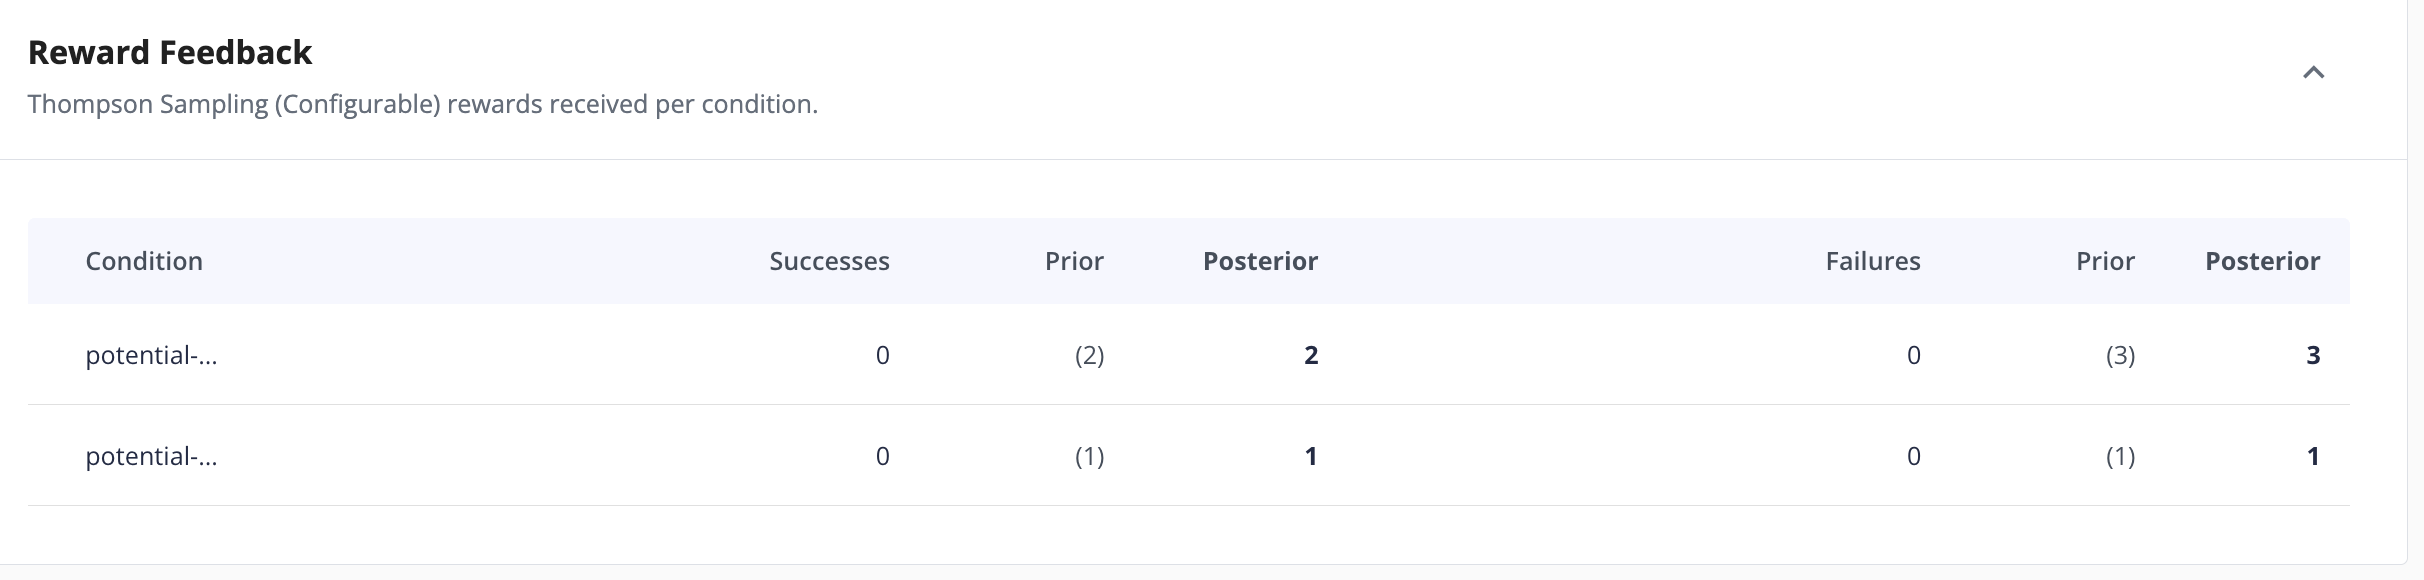
#### Reward Feedback